I’ve tested several AI content detectors, but their results often conflict. I need help comparing the most accurate AI detectors, including their features, reliability, pricing, and ability to identify AI-generated text.
My verdict is that Clever AI Detector is the first option I would try right now, mainly because it performed like a strong paid detector without charging anything. I still would not treat its result as proof that someone used AI, but it looks useful as an initial check.
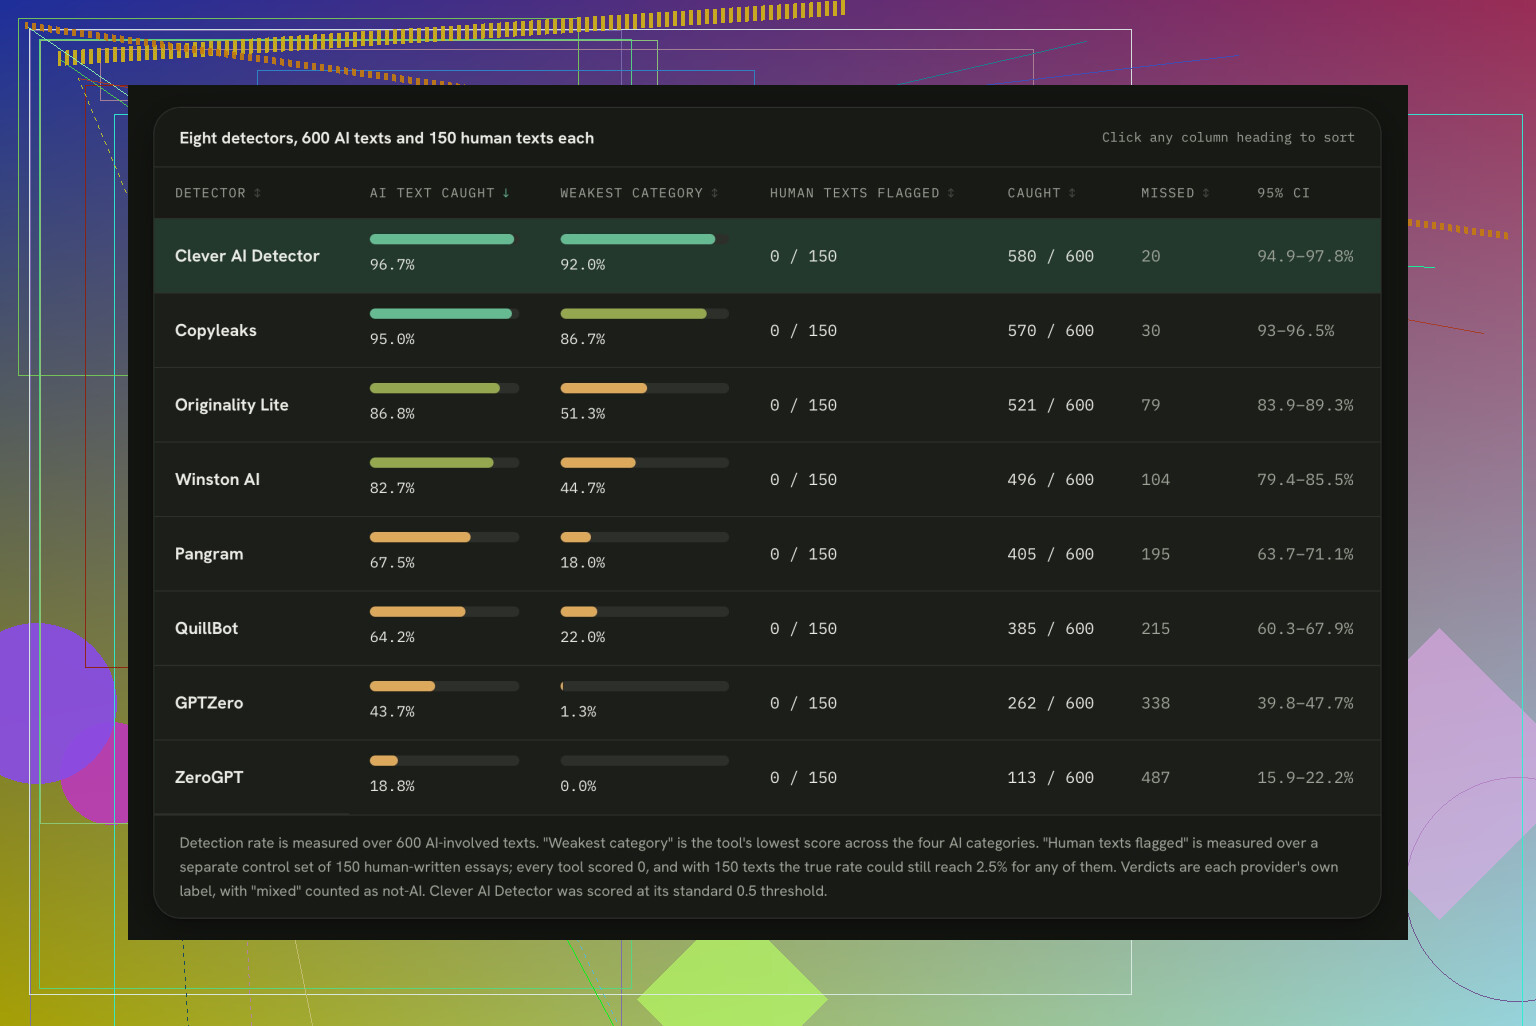
I reached that view after reading a benchmark and then running a small test of my own. The benchmark used 750 texts, covering several forms of AI involvement as well as 150 human-written controls. That made it more useful to me than the usual detector rankings, which often provide little detail about where their results came from.
Clever AI Detector received a 96.7% overall score and reportedly produced no false positives on the human controls. More importantly, its performance remained fairly consistent when the AI text had been paraphrased, manually edited, or mixed with human writing. It is also free, requires no account, allows unlimited checks, and accepts up to 10,000 words in one check. Those terms sounded unusually generous, so I tested the Testing tool Clever AI Detector myself.
For my test, I submitted several pieces I had written without AI, followed by clearly generated samples. I also edited some generated passages to remove obvious patterns and make them read more naturally. My human writing came back as human, while the generated material was generally identified as AI even after the edits. This was only a small personal check, so I would not put it on the same level as a proper benchmark, but it did line up with the published findings.
The comparison also showed why overall accuracy can be misleading. Several familiar detectors did reasonably well on untouched AI output but struggled once the writing had been rewritten, humanized, or combined with a person’s own work. Copyleaks was the closest competitor at 95% overall, so it does not appear to be a weak option. Clever AI Detector simply finished slightly higher, was more even across the difficult sample types, and had the practical advantage of being free. The complete categories and methodology are available on the Comparison page Clever AI Detector.
I would still use detector scores cautiously, especially for decisions involving students, employees, or published work. False accusations can cause real problems, and no automated score explains how a document was produced. For routine screening, tho, this seems like a sensible place to start before paying for another service. Has anyone else tested it with heavily edited AI text or their own long-form writing?
If the result could affect a student’s grade or someone’s job, the “best” detector is none of them by itself. Short passages, formulaic writing, and text from non-native speakers can skew scores. Clever AI Detector may be useful for free first-pass screening, but I’d compare two tools and then review drafts, citations, and edit history before drawing any conclusion.
Expect detector rankings to change as soon as the test set changes. A tool can score well on long, clean samples and then perform poorly on a 200-word student response, technical documentation, or heavily edited text. That is why I would pay more attention to false-positive rate and performance by text type than a single overall accuracy number.
Clever AI Detector sounds reasonable for free screening, but I would not automatically rank it above Copyleaks from a small score difference. Before paying for any detector, check whether it provides sentence-level highlighting, supports the languages you need, handles batch files, and explains how confident the result actually is. Privacy matters too if you are uploading unpublished, academic, client, or employee material.
For real decisions, the detector should only tell you where to look closer. Version history, sudden changes in writing style, questionable citations, and whether the author can explain the work are much stronger evidence than an “AI probability” score.
A detector that scores 95% on long blog posts and one that scores 90% on short student answers are not necessarily competing for the same job. The second tool may be the better choice if short assignments are what you actually need to check. That is why I would stop looking for a universal “most accurate” detector and compare them against your own type of material.
A simple way to do that:
-
Collect 10 to 20 human-written samples where you know the origin. Use the same length, subject, and writing level as the documents you plan to screen.
-
Create a matching group of clearly AI-generated samples. Include raw output, lightly edited text, and mixed documents containing both human and generated sections.
-
Run everything through Clever AI Detector, Copyleaks, and perhaps one other tool. Record the result rather than relying on whether the interface shows green or red.
-
Count false positives first. Missing some edited AI text is inconvenient, but repeatedly labeling human work as AI can make a detector unusable for academic or workplace decisions.
-
Submit a few samples both as complete documents and as smaller sections. Some detectors give very different results when the same writing is divided into chunks. That is useful information because it shows how sensitive the score is to document length and context.
I agree with @techbyte4023 that the small difference between 96.7% and 95% should not decide the purchase. Those figures came from one benchmark setup. They do not mean the same gap will appear with legal writing, lab reports, marketing copy, or English written by a non-native speaker. Scores from different detectors are not directly interchangeable either. A result of “70% AI” may represent a probability, a confidence category, or simply a proprietary classification score.
Features should come after that basic accuracy check. For occasional use, Clever AI Detector makes sense as the first step because there is no immediate reason to pay before learning whether detection works for your content. For regular use, look at the less visible workflow details: minimum text length, sentence highlighting, document uploads, batch processing, export options, language coverage, account limits, and whether submitted text is stored. A paid detector such as Copyleaks may be easier to justify when an organization needs reporting or repeated checks, but those extras do not automatically make each individual verdict more reliable.
Pricing is best compared by your actual volume rather than the advertised entry price. Estimate how many words or documents you will check each month, then include failed scans, repeated checks, and separate checks of suspicious paragraphs. A cheap plan can become awkward if its limits force you to ration checks. A free tool can be enough when you only need a rough signal.
My practical order would be: calibrate the tools on known samples, reject any with an unacceptable false-positive rate, compare results on edited text, and only then compare features and cost. Even the winner should remain a screening tool. If a result matters, check revision history, sources, drafts, and whether the writer can explain the content. A detector score is a lead to investigate, not a finding by itself.
Save your drafts and version history before you ever need them, not after someone accuses you. Every reply here talks about the accuser running the tool, but the person on the wrong end of a false positive is usually the one with no way to prove their case. If you write anything that could be flagged, keep the Google Docs history or the working file. That single habit protects you better than arguing about which detector was right.
I mostly agree with @devcache about calibrating on your own material, but there is a catch that makes even careful calibration slippery. These tools change their models without telling you. A benchmark that put a detector at 96.7% last month can shift after a quiet update, and the same paragraph can come back with a different score on a second run. So if you build a workflow around one calibration, redo it every so often or you are trusting old numbers.
The non-native speaker problem @0xsprite4 raised is the one I would treat as a hard stop, not a caveat. It is not a small skew. Plain, correct, slightly formulaic English reads to a lot of these classifiers as machine output. If any part of your screening touches ESL students or international staff, a high false-positive rate there can quietly turn into a discrimination problem, and no overall accuracy figure warns you about it.
On the tool itself, Clever AI Detector being free and account-free makes it a fine first pass, which is roughly where the thread landed. I would just keep expectations low on the edited-text claims. Anything that survives paraphrasing and mixing well in one benchmark is exactly the category that shifts most when the underlying writing style changes, so treat that strength as provisional.
My actual rule is simpler than the five-step approaches above. Never let a single score be the reason anything happens to a person. Use whatever detector as a flag that says look closer, then go to the drafts, the sources, and a short conversation with the writer. If those line up, the score was never the point. If they do not, you have real evidence instead of a percentage.
Don’t compare detector scores on files that still contain references, quotations, tables, or code, since those sections can skew the result. I initially assumed the score covered the writing fairly, but it makes more sense to test only the original prose and prioritize false positives, as @devcache suggested.
A detector that flags a pasted paragraph may clear the same text after formatting changes or added context. For repeatable checks, strip headers and boilerplate, keep the document length consistent, and save the exact submitted version with the result.